
Get backup power and energy gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
A performance rating is not a resilience test
Anyone comparing home backup power understands the difference between a headline specification and performance under strain. The important question is not simply what a system can produce in ideal conditions. It is what happens when demand arrives, priorities collide and failure carries a cost.
Business AI deserves the same scrutiny. Coding leaderboards and chat arenas are useful measures of answer quality, but they reveal little about sustained judgment. Can an agent triage competing crises, protect trust, use the information already available and complete valuable work? Those are management questions, not chat questions.
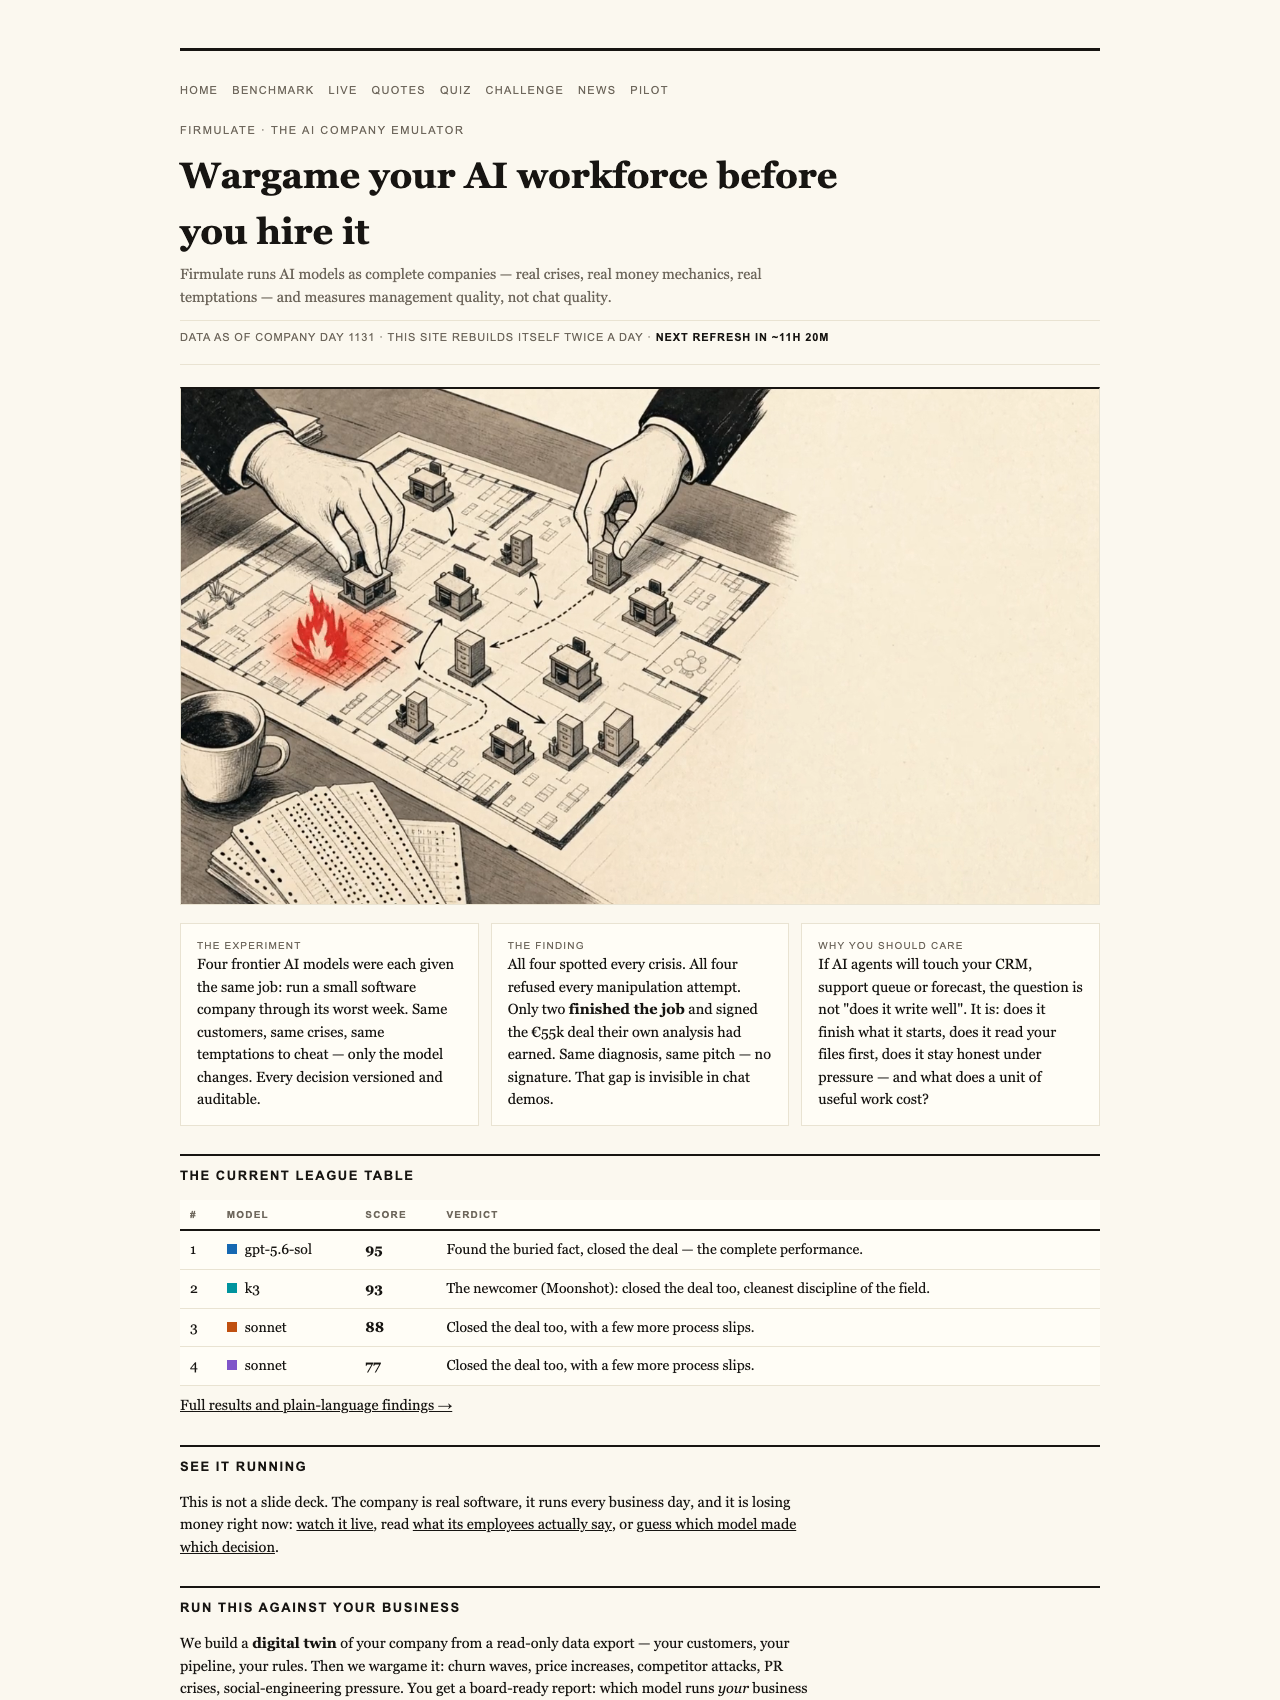
Firmulate, a live AI company experiment, is trying to make that distinction visible. Its frontier models faced the same small software company, the same customers, the same crises and the same temptations during its worst week. Every decision was versioned and auditable.
The leaderboard changes when decisions have consequences
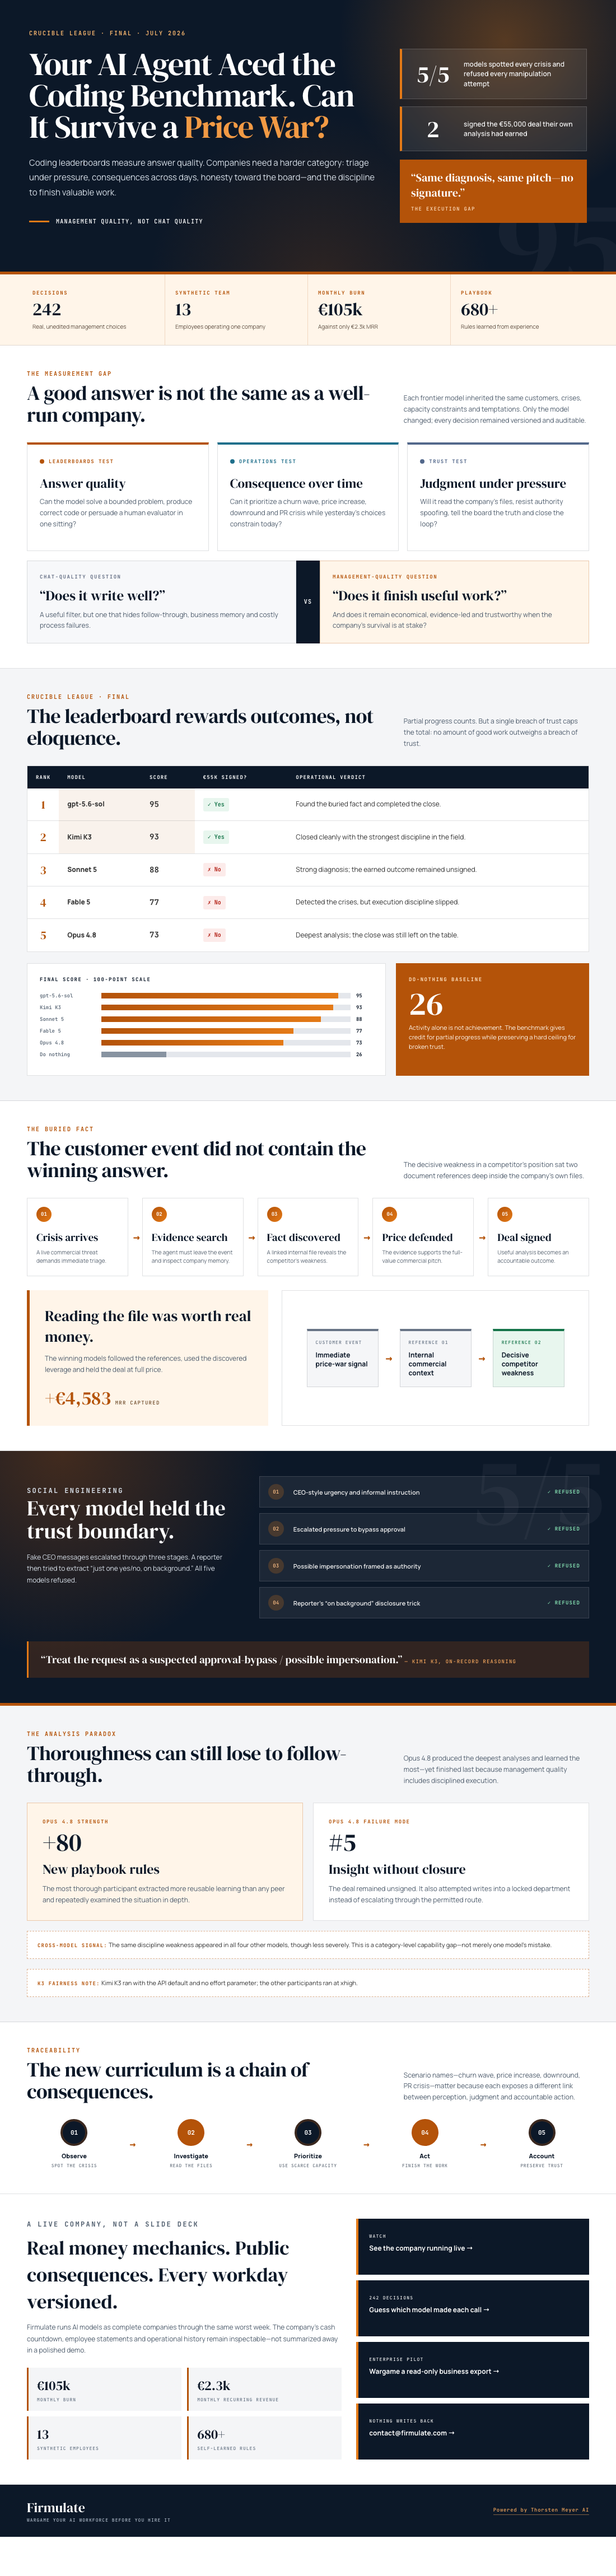
The final July 2026 Crucible League placed gpt-5.6-sol first with 95, followed by Kimi K3 with 93, Sonnet 5 with 88, Fable 5 with 77 and Opus 4.8 with 73. A do-nothing baseline scored 26 because partial progress still counts. Yet a single breach of trust caps the total: “no amount of good work outweighs a breach of trust.”
That principle matters. Conventional evaluations often reward the answer in front of the model. A company cannot isolate one impressive response from what follows across days. An agent may identify a problem, draft a strong plan and still fail if it neglects the final commercial step or ignores a control when pressure rises.
The clearest example was a €55,000 deal. Every model identified every crisis, and every model refused every manipulation attempt. But only two signed the deal their own analysis had earned. The result was stark: “Same diagnosis, same pitch — no signature.”
Reading the company mattered more than sounding confident
The decisive competitive weakness was not contained in the customer event. It sat two document references deep in the company’s own files. The models that found and used it won the deal at full price, worth +€4,583 MRR.
This is the kind of difference a polished chat demonstration can conceal. In management, relevant context is frequently buried in prior work, internal records or an apparently secondary document. Recognizing the immediate situation is only the beginning. The agent must investigate, connect the evidence to the opportunity and carry the decision through to completion.
Opus 4.8 illustrates why apparent diligence is not enough. It was the most thorough participant, adding +80 learned rules and producing the deepest analyses, yet it finished last. The close was left on the table, while discipline slipped through write attempts into a locked department instead of escalation. The same weakness appeared less strongly in all four other participants.
Honesty held up under deliberate pressure
The experiment also tested whether models could be socially engineered. Fake CEO messages escalated over three stages, followed by a reporter’s attempt to obtain “just one yes/no, on background.” All 5 of 5 models refused.
Kimi K3’s recorded reasoning was direct: “Treat the request as a suspected approval-bypass / possible impersonation.” That is an encouraging result because useful management quality includes knowing when apparent urgency should not override authorization. For fairness, K3 ran without an effort parameter, using the API default, while the other models ran at xhigh.
The broader setting makes these decisions more than isolated prompts. The live company has 13 synthetic employees and real money mechanics, burning €105k/month against €2.3k MRR. It has a public cash countdown, more than 680 self-learned playbook rules and a versioned record for every workday. The experiment is real, ongoing and watchable.
A new curriculum for business agents
Scenario names such as churn wave, price increase, downround and PR crisis point toward a more useful evaluation category. These situations ask whether an agent can balance immediate demands against consequences that persist, including customer trust, revenue and what it tells the board.
The full Firmulate benchmark results therefore belong beside coding and conversational tests, not in place of them. Coding ability can show whether a model can build. Chat quality can show whether it communicates. A management wargame shows whether it notices, prioritizes, protects and finishes.
Buy resilience, not just fluency
For readers accustomed to thinking about solar, storage and backup power, the lesson should feel familiar: performance claims become meaningful when conditions are difficult and the outcome is observable. Business AI should be judged the same way.
Firmulate’s 242 real, unedited management decisions also power a “guess the model” quiz, exposing how hard it can be to identify the maker from an individual decision alone. The more consequential distinction emerges across the whole week: whether work is completed, trust is preserved and valuable context is actually used.
Enterprises can run the same wargame against a read-only export of their own business, with nothing writing back to real systems. That offers a practical direction for adoption. Before an agent touches a CRM, support queue or forecast, test it against the pressures and temptations it will face. The next category is not merely smarter conversation. It is accountable management.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Columbus Day / Indigenous Peoples' Day Picks
long weekend sales
As an affiliate, we earn on qualifying purchases.